Runware makes AI compute cost less
Runware bundles model APIs, serverless GPUs and dedicated clusters behind one key, running on modular data centers it designs itself.



One inference stack, owned end to end
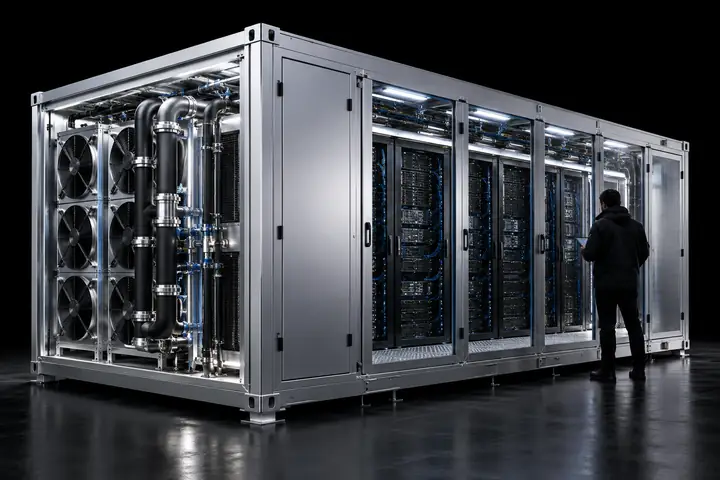
Runware operates all four layers. Its scheduling software and the modular Sonic Pods combine into the Sonic Inference Engine®.
Explore the engineMix modalities in a single call.
Each request is an array of tasks, so a picture, a clip and a chat reply can share one round trip. REST for stateless jobs, WebSockets for long sessions, webhooks per task.
A single schema for every model.
Auth, parameters and errors behave the same for open checkpoints and partner models alike.
Weights kept warm in every region.
Popular models stay loaded near users, so jobs skip cold starts.
Hardware designed and run in-house.
Containerised GPU modules that deploy fast and run lean.
Scale and reach in numbers
400K+
Models on one endpoint: open weights, frontier, partner and your uploads.
300M+
People reached by apps that run inference on Runware.
5 modes
Image, video, audio, text and 3D through one request format.
99.99%
Reported platform uptime over the trailing 90 days.
400K+ models, one Runware API
Every provider shares the same auth, schema and invoice. Trying another model means editing one string.
[
  {
    "taskType": "imageInference",
    "model": "runware:400@1",
    "positivePrompt": "machinery, lime-to-amber glow",
    "width": 1024
  }
]
Serverless GPUs for
every AI workload
Ship containers and weights onto the same modular GPUs behind the Runware API. Usage is metered per second and scales to zero when idle.
Bring your workload
Package a container or upload weights, then serve without provisioning a machine.
On Sonic
hardware
Zero
Idle GPUs · when traffic stops
Lean by construction. Runware rebuilt the stack around modular hardware and tight scheduling, and hands the efficiency to the teams running on it.
Explore serverlessReserved GPUs: serverless or bare metal
Pay-as-you-go suits spiky traffic. Once your baseline is clear, commit instead: guaranteed GPUs on the shared pool, or a private cluster of Sonic Pods.
Committed serverless
Guaranteed GPUs · shared pool
- Hold a set number of GPUs for a fixed term, even at peak demand.
- Overflow beyond the reservation runs on demand.
Frontier GPUs
Custom builds on Sonic Pods
- Dedicated clusters from 72 GPUs, with your own stack on the metal.
- Current parts: Vera Rubin NVL72, GB300 NVL72 or HGX B300.
Modular data centers at roughly half the cost
Its own hardware, its own engine, identical models — reported at up to 90% under typical market rates.
Model / workload
~92%
lower spend, illustrative
Largest gaps vs market rates
Plugs into where you already build.
Hand the wiring to an agent. Point Claude Code, Cursor or another MCP client at Runware, paste a key, and generate within minutes.
✓ tools · run · list_models · model_schema
>Animate the hero still into a 6-second clip, then layer ambient sound.
·list_models capability=image-to-video
Customers
“Our community expects every checkpoint the day it lands. Sampler, LoRA, odd setting — elsewhere that meant stitching endpoints together. Runware puts it all behind one call.”
No training
On customer data
SSO + SAML
Enterprise login
SOC 2
Audited
ISO 27001
Certified
GDPR
Aligned
24/7
Engineer support
Reach millions of users this afternoon.
Runware serves inference near your audience, with no GPUs to provision and usage that tracks demand.
FAQs
Questions developers raise before the first request. Deeper detail sits in the docs.
What does “one API for every model” actually mean?
Runware exposes image, video, audio, text and 3D models through a single endpoint and schema. Switching models is a one-field edit.
What exactly is the Sonic Inference Engine®?
It is the name Runware gives its orchestration layer paired with Sonic Pods, so scheduling and hardware are tuned together.
Why is it cheaper if quality stays the same?
The models are identical. Savings come from purpose-built hardware, warm caching and tight scheduling, not from trimmed outputs.
What if my usage outgrows serverless?
Reserve GPUs on the shared pool or move to a dedicated Sonic Pods cluster, keeping the same API.
Will my inputs be used to train models?
No. Runware states that prompts, uploads and outputs stay out of training, with SSO and EU or US data residency available.